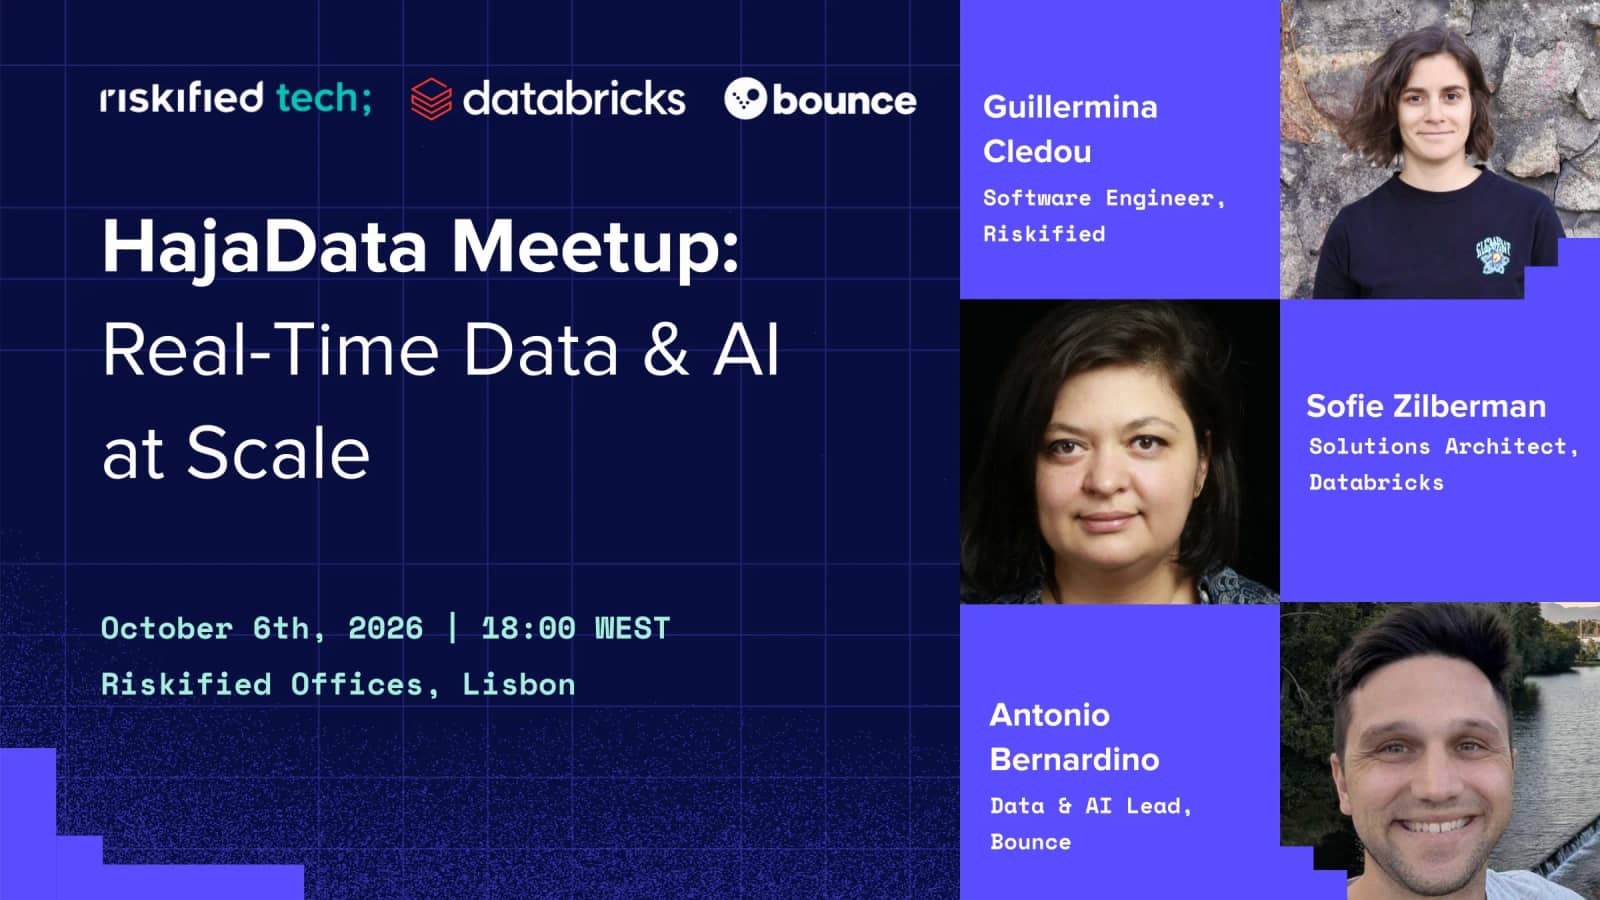
HajaData Meetup: Real-Time Data & AI at Scale
About the event
Please sign up here: [https://luma.com/e62lb3jg](https://luma.com/e62lb3jg)
Join us for another HajaData meetup in Lisbon, bringing together the local data community for an evening of technical talks, practical insights, and good conversations. This time, we’ll dive into the challenges of building and operating modern data systems at scale — from replaying real-time production flows over millions of historical events, through the evolving world of real-time streaming with Apache Spark and Flink, to what happens when AI agents start operating directly on top of the data warehouse. We’ll hear from engineers and data leaders from Riskified, Databricks, and Bounce, sharing real-world architectures, challenges, tradeoffs, and lessons learned along the way.
Please sign up here: [https://luma.com/e62lb3jg](https://luma.com/e62lb3jg)
---- Agenda: 18:00 - 18:30 - Mingling, drinks, and snacks 18:30 - 19:00 - Replay the Past, Validate the Future: Taking Online Flows Offline at Scale - Guillermina Cledou, Software Engineer at Riskified 19:00 - 19:30 - When Streaming Titans Collide: Spark 4.0™ and Apache Flink in the Age of Real-Time AI - Sofie Zilberman, Solutions Architect at Databricks 19:30 - 20:00 - Enabling Humans & AI Agents to Operate on the Data Warehouse at Scale - Antonio Bernardino, Data & AI Lead at Bounce 20:00 - More drinks and mingling The talks will be delivered in English.
---- // Replay the Past, Validate the Future: Taking Online Flows Offline at Scale - Guillermina Cledou, Software Engineer at Riskified What if you could take the same flows running online in production and replay them offline across millions of historical events? Real-time systems are built to process events as they happen, but understanding the impact of a change before it reaches production requires something very different, running that same production logic over massive amounts of historical data. Bridging these two worlds means turning online flows into scalable offline workloads, while keeping the behavior as close to production as possible. In this talk, we’ll share how we built a replay system that does exactly that, the architectural challenges we encountered, and the tradeoffs we made along the way. By the end, you’ll have practical patterns for bridging online and offline processing, reusing production logic at scale, and building replay systems that let you evaluate changes before they reach production.
*About the speaker:* Guillermina is a Software Engineer at Riskified, where she helps design and evolve the machine learning-based systems that decide millions of fraud cases a day. She has a computer science background and a research past, but these days she's happiest building the infrastructure that lets people test their ideas without holding their breath. // When Streaming Titans Collide: Spark 4.0™ and Apache Flink in the Age of Real-Time AI - Sofie Zilberman, Solutions Architect at Databricks For years, the line was clear: Apache Flink owned ultra-low-latency, event-driven processing while Apache Spark dominated high-throughput streaming. Spark 4.0 redraws this line. Real-Time Mode brings continuous low-latency processing to Structured Streaming, and the new transformWithState API delivers the flexible state management that event-driven systems demand. In this session, we will dive into a technical discussion of both Spark and Apache Flink, exploring Spark’s transformWithState and RTM alongside Flink’s mature event-time engine. As the two engines converge, we’ll examine what still sets them apart under the hood, in execution pipelines, in state backends, and in architectural philosophy, and, just as importantly, where those differences no longer matter in practice. Whether you’re optimizing a pipeline, upgrading to Spark 4.0, or architecting a greenfield platform to serve AI agents, you’ll leave with clear criteria for choosing the right engine.
*About the speaker:* Sofie designs and optimizes…